Text Models
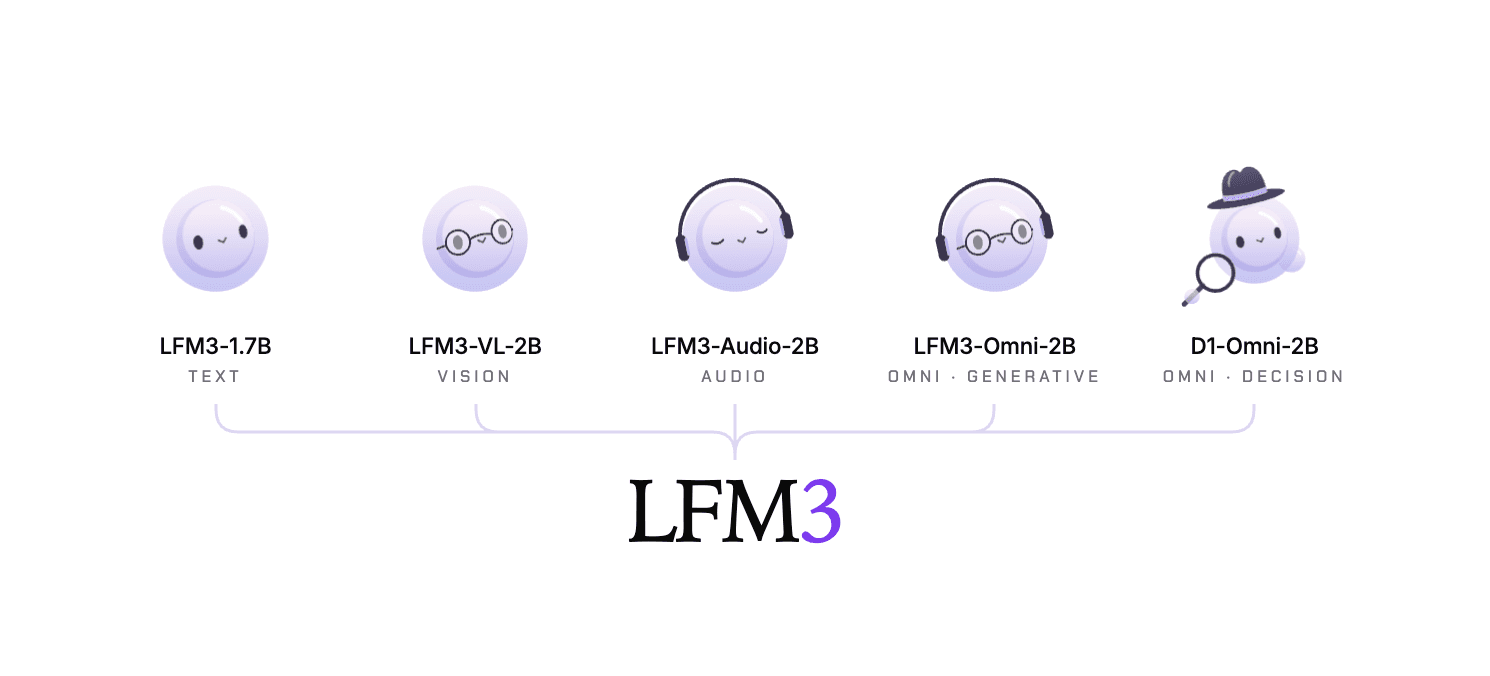
LFMs deliver powerful performance in a lightweight, customizable, and compute-efficient footprint for deployment in any environment.
Frontier-grade intelligence at a fraction of the compute, on any hardware, on or off the cloud.
LFMs deliver powerful performance in a lightweight, customizable, and compute-efficient footprint for deployment in any environment.
Purpose-built models for classification, routing, and scoring. One API call returns calibrated probabilities across a fixed set of outcomes.
End-to-end foundation model for audio and text generation. Designed for low latency, it enables responsive, high-quality conversations with only 1.5 billion parameters.
Tiny customized models for specific tasks and knowledge.
Every LFM is free to download, run, and fine-tune — including commercially — until your company passes $10M in annual revenue. See pricing & licensing

Explore more quants, runtimes, modalities, and metrics on Pipette.
GGUF, MLX, and ONNX builds run on laptops, phones, and edge boxes with no key.
The fastest way to start. Get a key from Liquid Console, then call our models over an OpenAI-compatible endpoint.
Serve many requests at once. Run your own GPU server, or let a platform handle the hardware.
SM8850 · 12 GB RAM · llama.cpp b11988 · 1K-token prompt + 256-token reply · live from Pipette
Pareto frontierExplore more quants, runtimes, modalities, and metrics on Pipette.
See the full leaderboard