Text Models
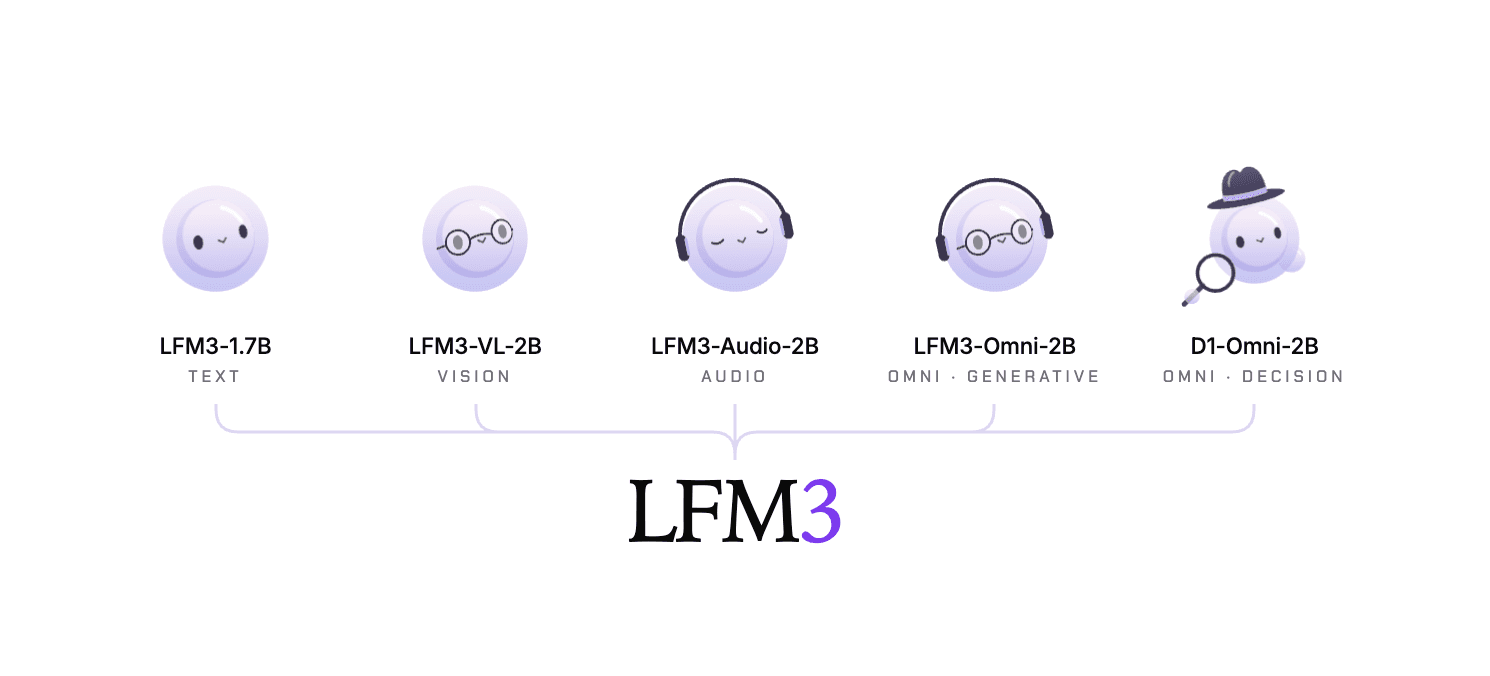
LFMs deliver powerful performance in a lightweight, customizable, and compute-efficient footprint for deployment in any environment.
Frontier-grade intelligence at a fraction of the compute, on any hardware, on or off the cloud.
LFMs deliver powerful performance in a lightweight, customizable, and compute-efficient footprint for deployment in any environment.
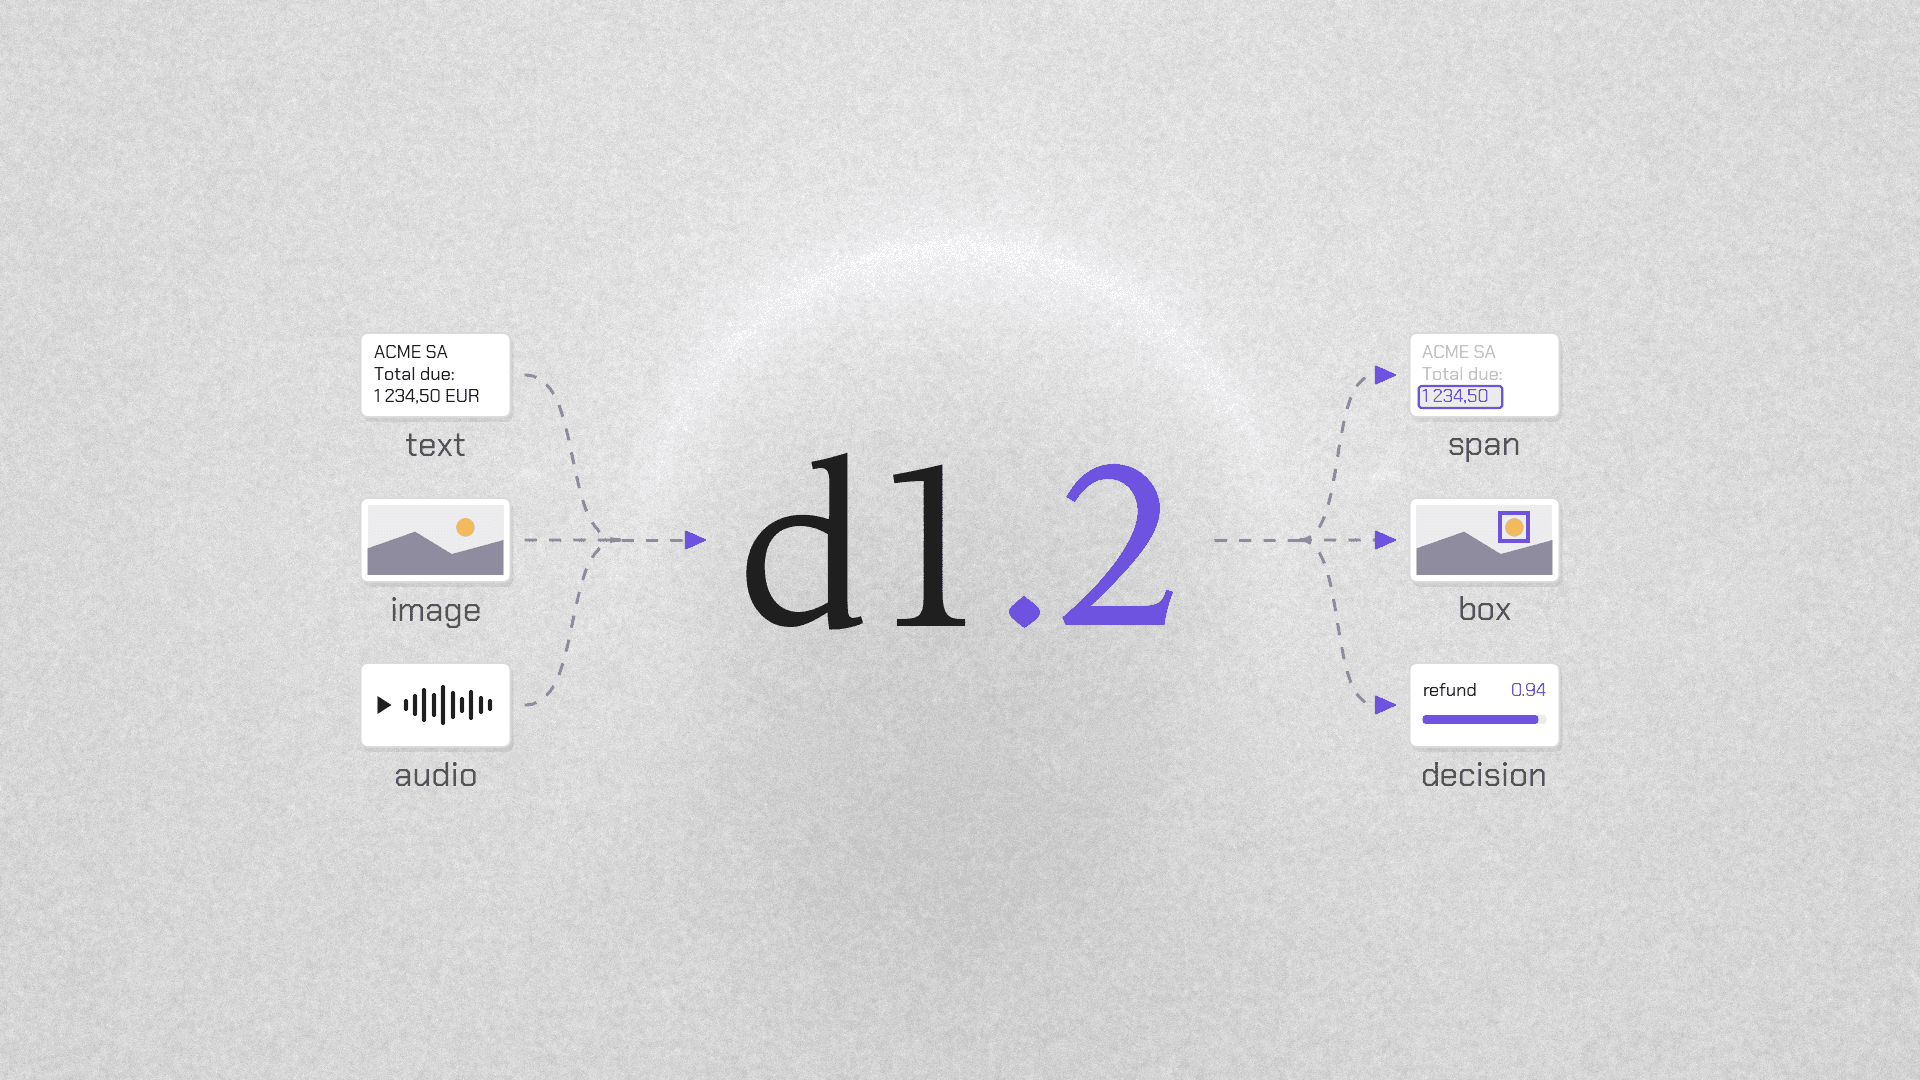
Purpose-built models for classification, routing, and scoring. One API call returns calibrated probabilities across a fixed set of outcomes.
End-to-end foundation models for audio and text generation, designed for low-latency, responsive, high-quality conversations.
Tiny customized models for specific tasks and knowledge.
Every LFM is free to download, run, and fine-tune — including commercially — until your company passes $10M in annual revenue. See pricing & licensing

Explore more quants, runtimes, modalities, and metrics on Pipette.
SM8850 · 12 GB RAM · llama.cpp b11988 · 1K-token prompt + 256-token reply · live from Pipette
Pareto frontierExplore more quants, runtimes, modalities, and metrics on Pipette.
See the full leaderboard